Turn Your Daily Digest Into a Podcast You'll Actually Listen To
A Copilot Studio Skill that turns documents, emails, and press releases into a podcast episode with two hosts in conversation — from multi-voice SSML and Azure Text to Speech to listening on your phone.
Translated article — This article is based on Turn Your Daily Digest Into a Podcast You’ll Actually Listen To by raemone (@raemone) on The Custom Engine (2026-07-28). The original wording takes precedence.
Every morning at 7:12, a press review lands in my inbox. Fifteen headlines, three paragraphs each, clearly curated by someone who cares. And every morning, I open it, scroll to the bottom in about four seconds, and tell myself, “I’ll read it properly later.”
I never read it properly later.
The frustrating part is that every day I have a perfect 40-minute window where my eyes are busy but my ears are not: the commute, the treadmill, cooking. It is more than enough time to absorb everything in that email, but none of it is time I can spend reading.
So I built an agent that takes the email and hands me back a podcast episode: two hosts, actual conversation, roughly six minutes, playing in my headphones on the train.
Today’s menu:
- What I was actually after — and why a summary is not it
- The Azure Speech endpoint — creating it and wiring it into the agent
- The Skill — what it does, and why it had to be a Skill
- Publishing to Teams and M365 Copilot so it lands on your phone
- The SSML details that decide whether it sounds like a podcast
This one needs the GitHub Copilot harness. The Skill works only in the GitHub Copilot harness, not the Standard harness, and the whole experience depends on Skills. If you have not tried it yet, treat this as a preview rather than a build guide.
The thing I actually wanted
Let me be precise about the goal. It is not “summarize this email.” I have tried having agents summarize that press review before. What comes back is a bulleted list, which is perfectly fine to read and terrible to listen to. Bullets read aloud sound like a fire drill.
What makes something listenable is friction between two people. One person says a number, and the other says, “Wait, off what base?” That exchange is what makes a fact stick. It is why the NotebookLM audio overview format spread so quickly, and it is the format I wanted for my inbox.
So the agent produces three things:
| Artifact | What it is for |
|---|---|
<slug>_Podcast_Script.txt |
The human-readable transcript, with NOVA: / MILES: labels so you can skim it before listening |
<slug>_Podcast.ssml |
The machine artifact: multi-voice SSML that can go straight to a text-to-speech service |
<slug>_Podcast.wav |
The narrated episode, if you want it generated |
The source can be almost anything: a newsletter, a press review, a set of articles pasted into chat, a PDF, a document. Or nothing at all, if you just want an episode about a topic. I used it on a 12-page architecture document I was supposed to review before a meeting, and it genuinely prepared me better than skimming would have.
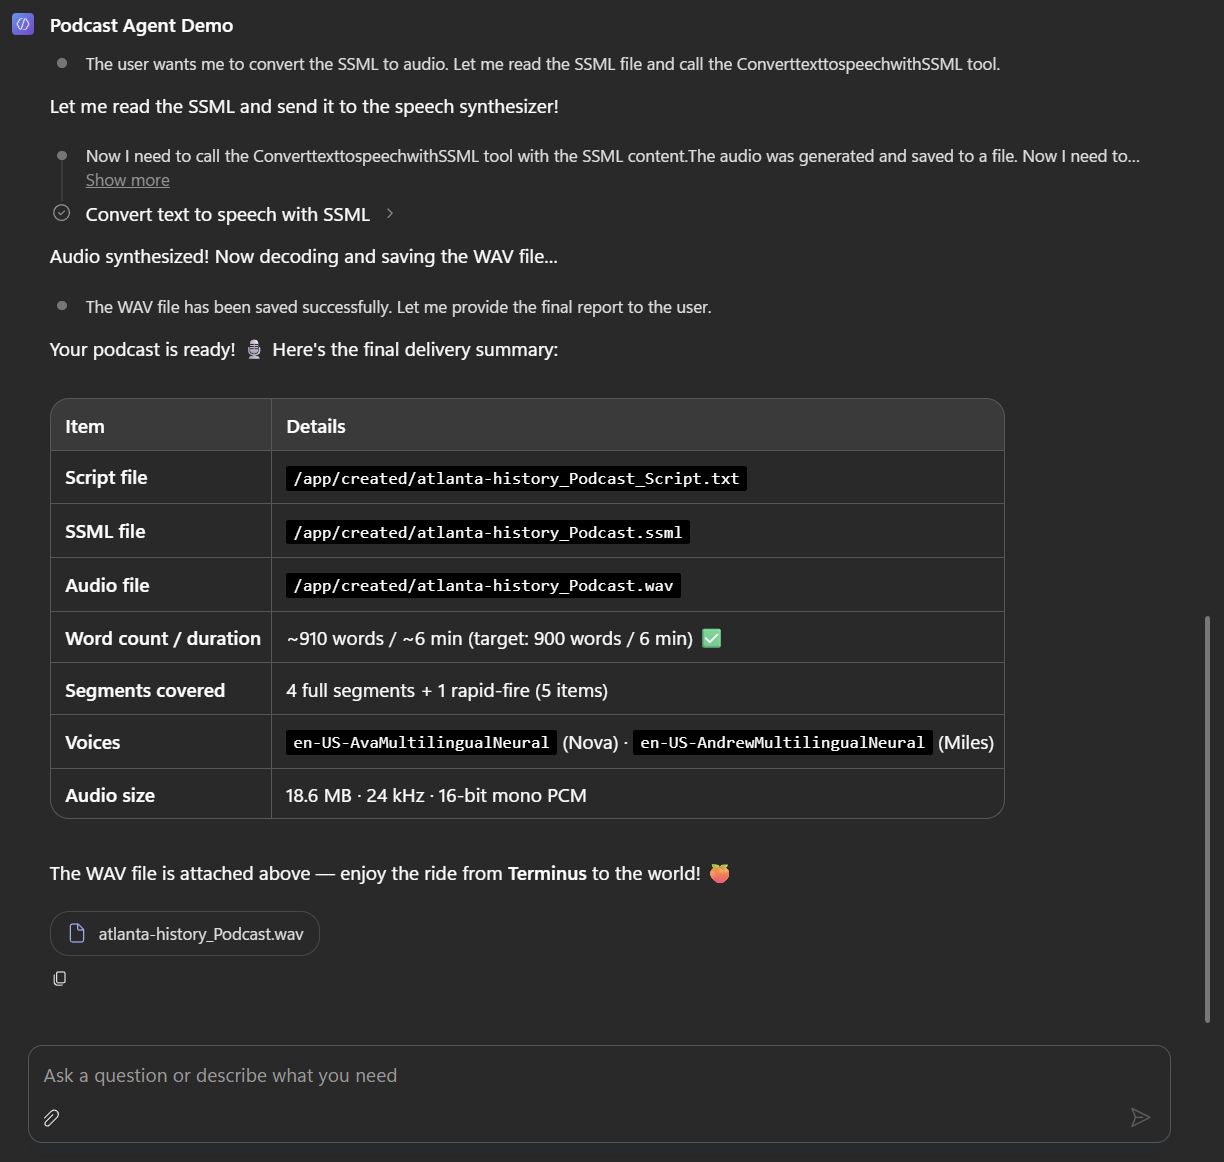
Here is the finished result first, so you know what we are aiming for.
Part 1: The Azure Speech endpoint
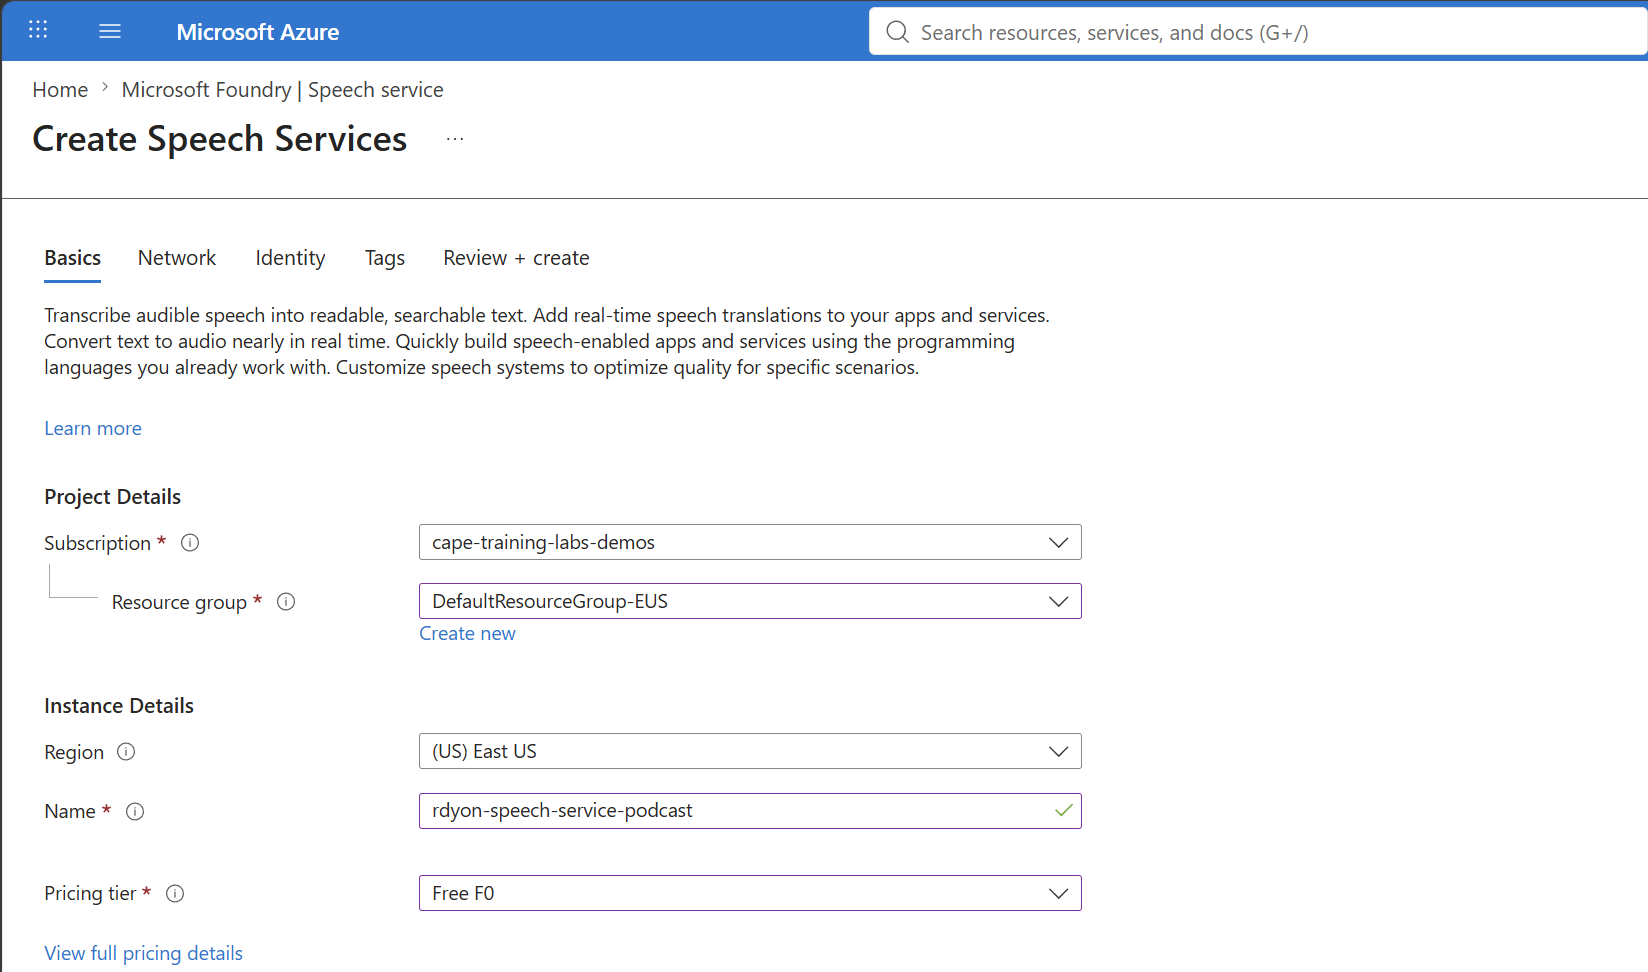
The agent needs somewhere to synthesize audio. An Azure AI Speech resource does that, and it takes about three minutes to set up.
Create the Speech resource
In the Azure portal, create a Speech service resource. Two choices matter:
- Region. Pick one close to you and write it down. The connector asks for the short code (
westeurope,eastus, and so on), not the display name. - Pricing tier. The free tier includes a monthly allowance of neural text-to-speech characters, enough to prove the whole thing works before you commit to anything. A six-minute episode is roughly 5,000 characters of spoken text.
Grab the key and region
Once deployment completes, open the resource and go to Resource Management → Keys and Endpoint. You need only KEY 1 and the Location/Region value. The connector does not need the endpoint URL.
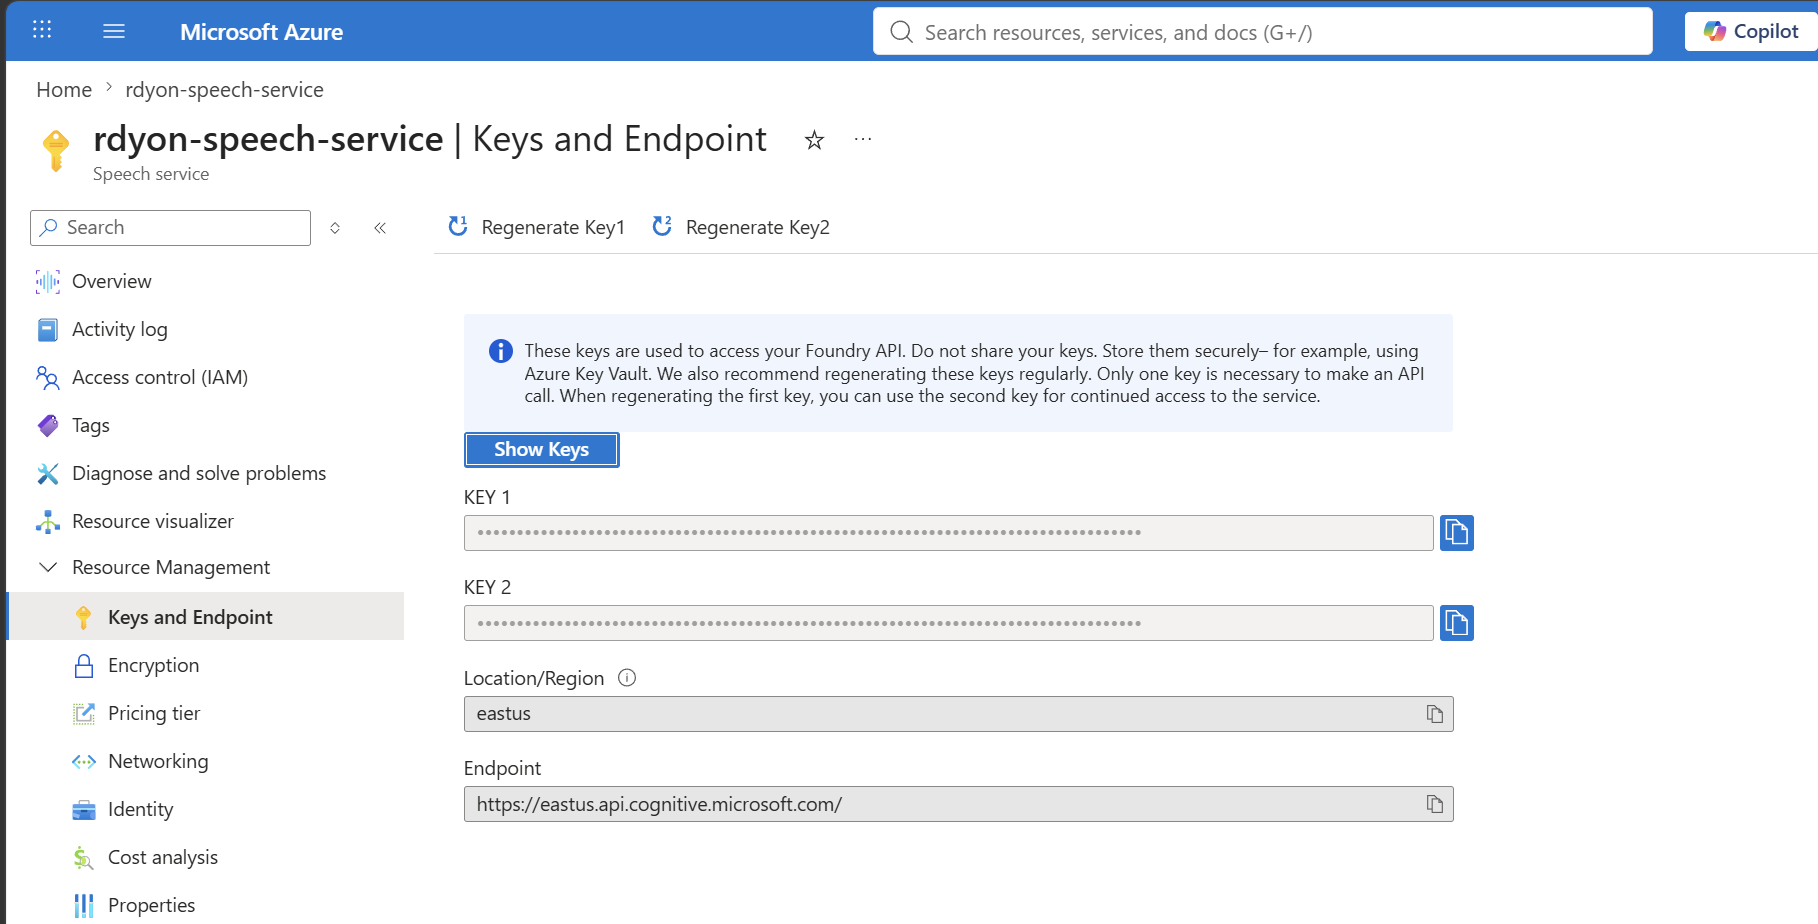
Treat the key like any other credential. Put it only in the Power Platform connection, never in a Skill file, instruction, or variable. If you would rather not handle a key directly, the connector also supports Microsoft Entra ID authentication against the resource ID. That is the better choice for anything beyond a personal demo.
Check that the voices are available
The default cast uses en-US-AvaMultilingualNeural and en-US-AndrewMultilingualNeural. Both are standard neural voices, but availability can vary by region, so it is worth checking the supported voices list for your selected region before going further.
Part 2: Wire the connector into the agent
Go to Copilot Studio. In your agent, go to Tools → Add a tool → Connector, and search for Azure Text to speech.
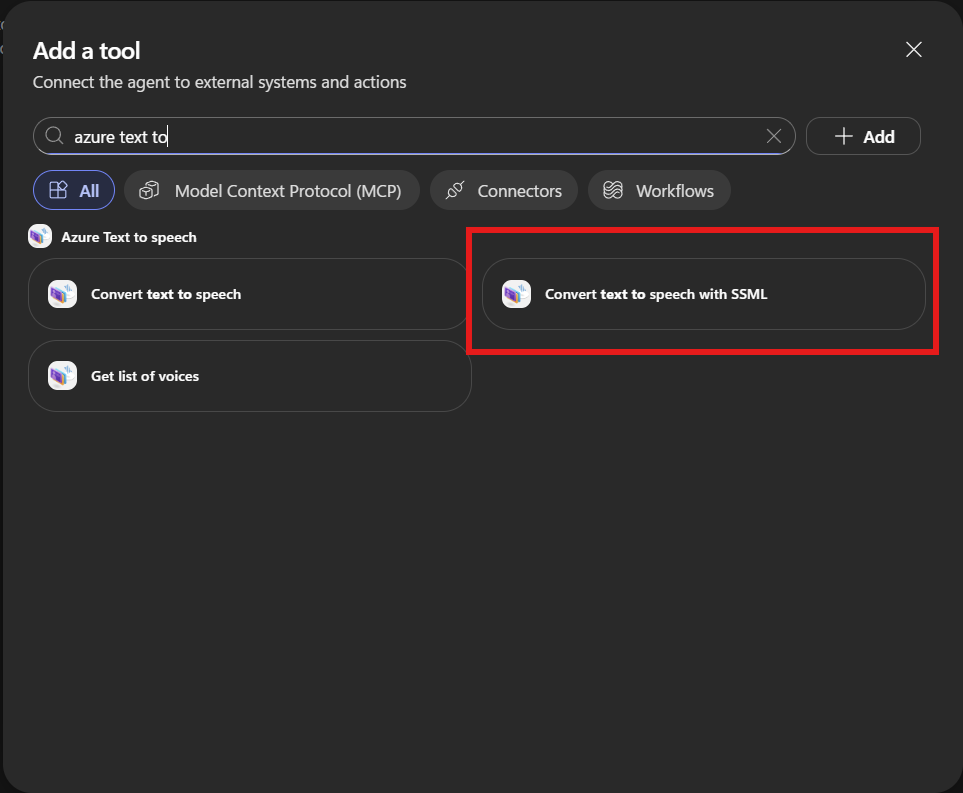
Add the Convert text to speech with SSML action. This is the one that matters. Its sibling, Convert text to speech, takes a plain string and a single voice name, which gives you one host reading in a flat monotone. The SSML action is what gives you two speakers, per-line prosody, and controlled pauses.
When creating the connection, choose API Key authentication and enter the two values from the Azure portal:
| Field | Value |
|---|---|
| Account Key | Key 1 from the Speech resource |
| Region | The region short code, for example westeurope |
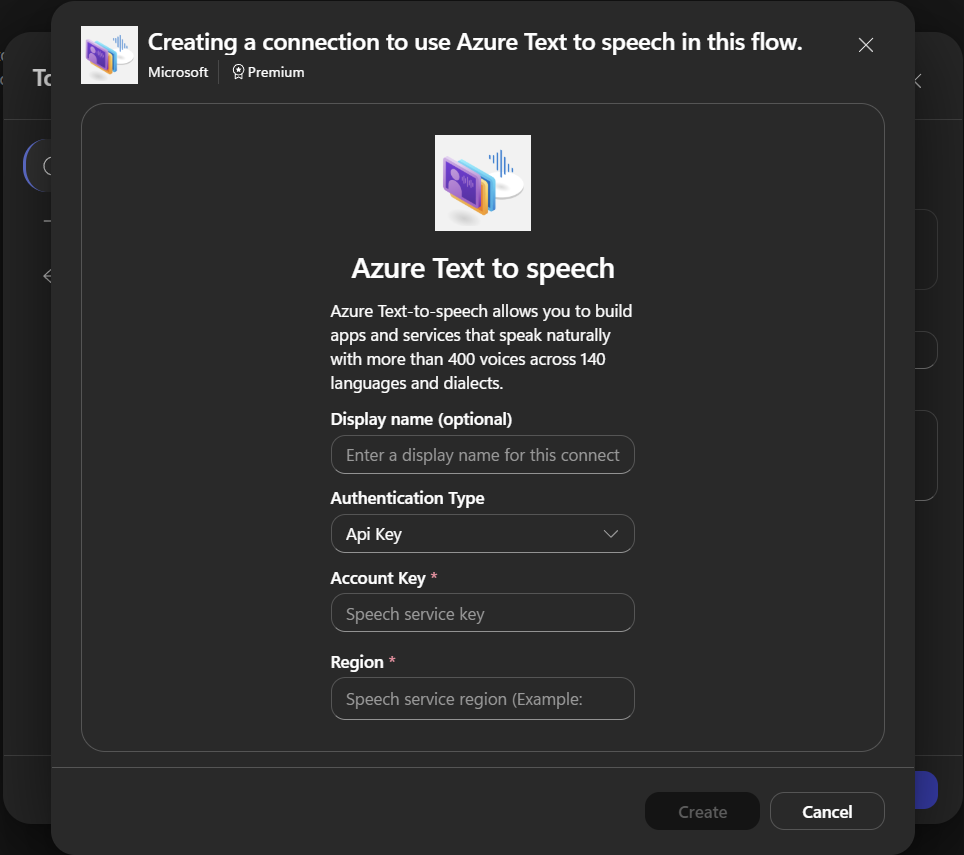
Two things to know before using this connector:
- It is a premium connector, so the usual Power Platform licensing rules apply.
- It is limited to 100 calls per connection per 60 seconds. Irrelevant for one episode a day, but important if you are considering batch-processing documents.
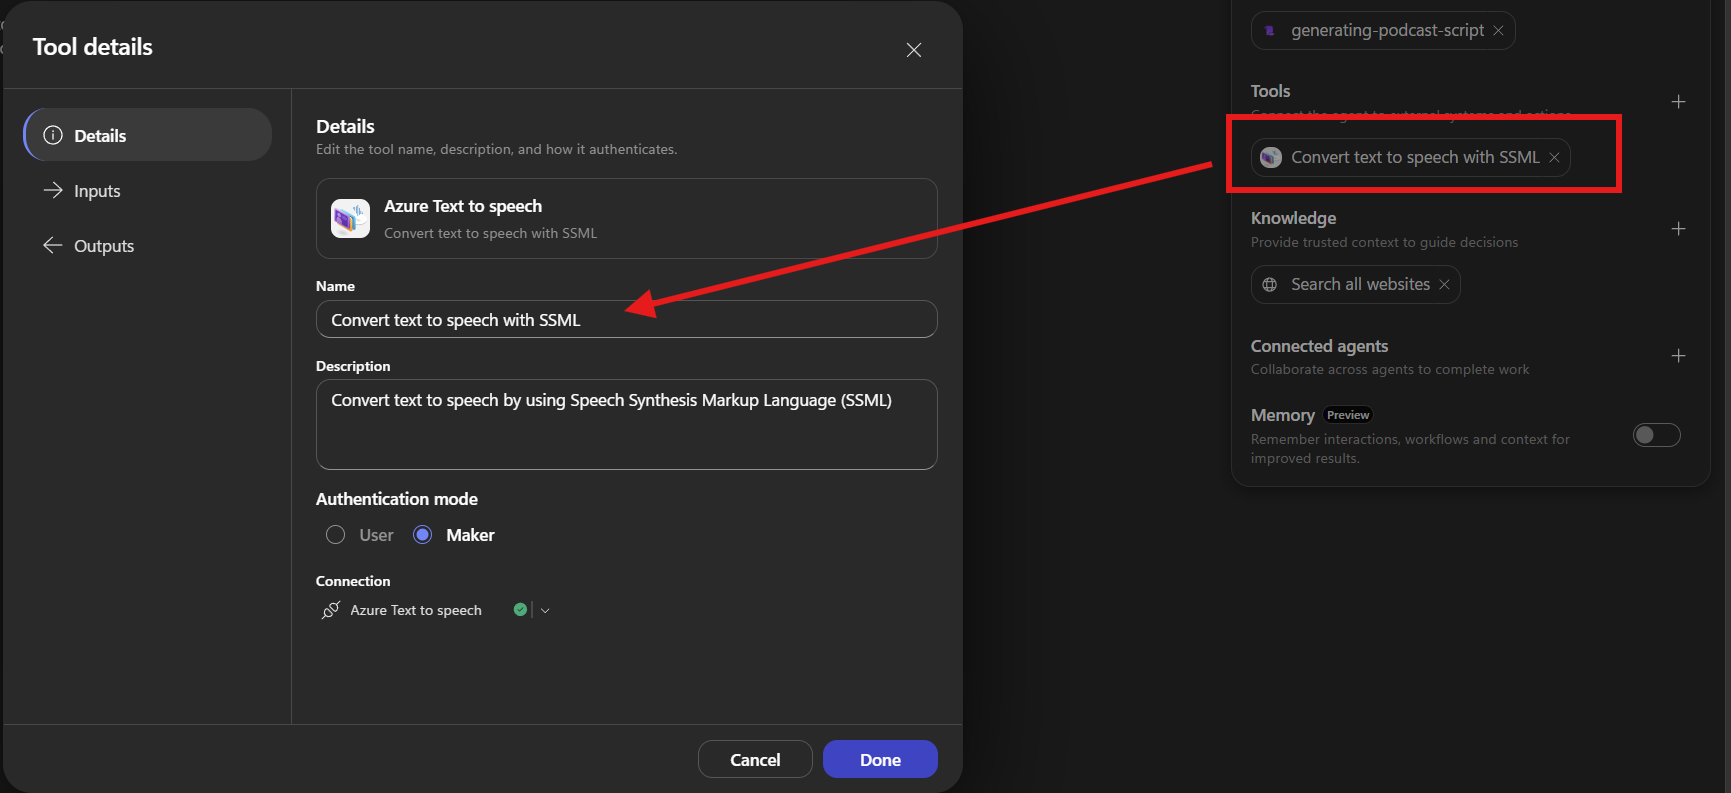
After the tool is added, check that its description still reads sensibly in the agent’s tool list. The agent selects tools based on descriptions, and the Skill instructs it to find this tool by name. If the description changes substantially, the handoff breaks.
Part 3: Add the Skill
The plumbing is ready; now for the interesting part: the instructions.
Why it had to be a Skill
You could write all of this in one agent instruction block. I tried. It was a bad idea for two reasons.
First, the guidance is long. Parsing source material, ranking items editorially, writing conversational dialogue, spelling out numbers for a synthesizer, and emitting valid multi-voice SSML add up to thousands of words of very specific procedure. If that sits in the agent instructions, it takes up context on every turn, including turns where someone just says “hi.”
Second, it is situational. Most of what my agent does has nothing to do with podcasts. Roel’s post on how Skills work in Copilot Studio states the rule well: guidance that applies to every conversation belongs in instructions; guidance that applies only to specific scenarios belongs in a Skill. This is about as scenario-specific as it gets.
Download and upload
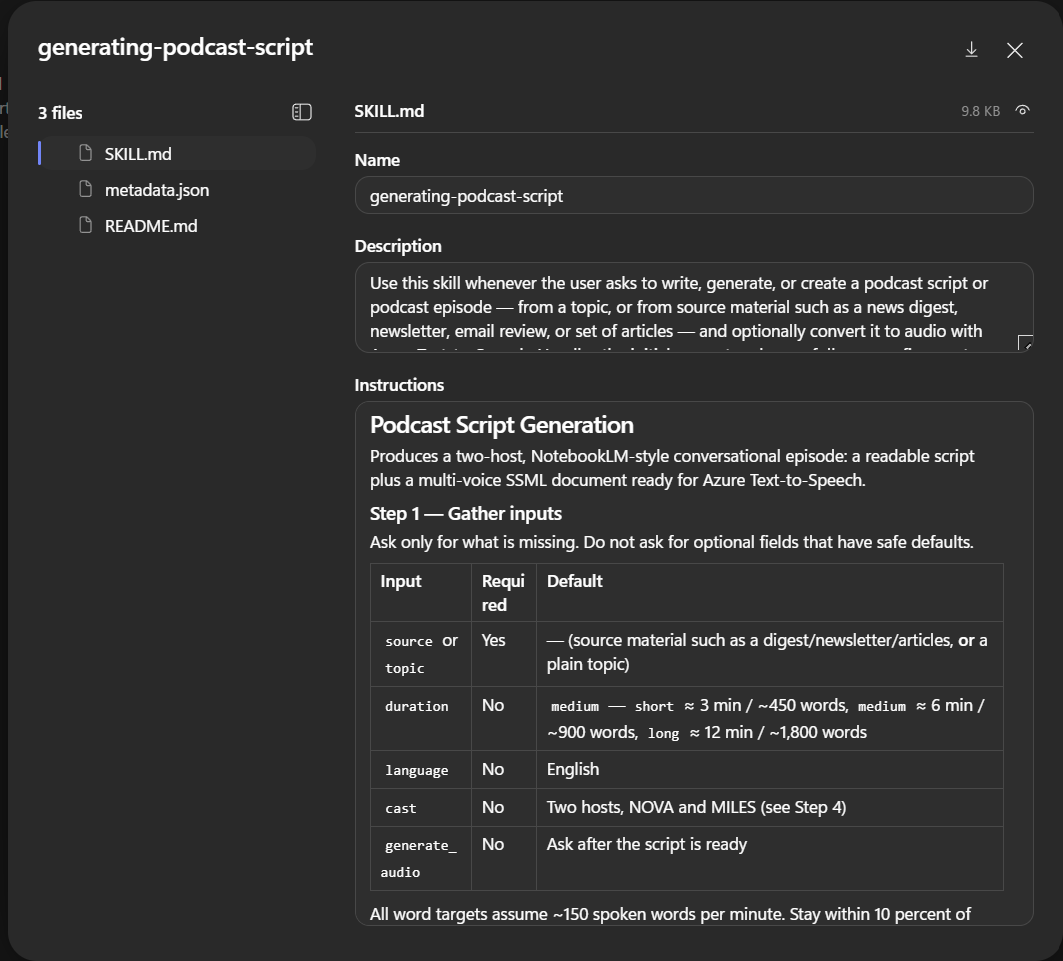
You do not have to write it from scratch. The Skill is published in the CAT Skill library: Podcast Script Generator. Download it there and you get exactly the files described below.
The Skill is a folder with three files:
generating-podcast-script/
├── SKILL.md        # front matter + the 11-step procedure
├── README.md       # human-facing explanation
└── metadata.json   # name, description, tags, version
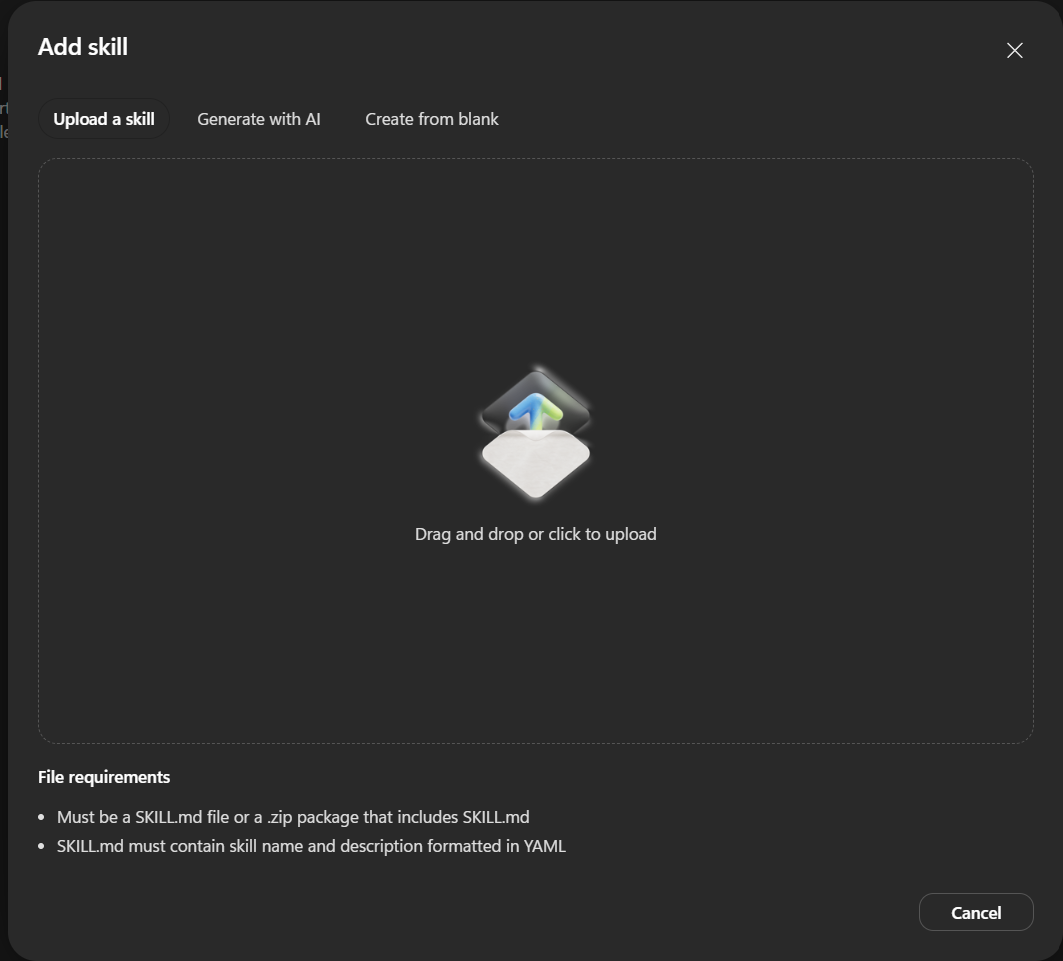
Zip the folder and upload it from the agent’s Skills tab via Add a Skill → Upload. A standalone SKILL.md also works, but the ZIP keeps the README and metadata together.
The routing signal is the description in the front matter, deliberately written to cover follow-up requests too:
name: generating-podcast-script
description: >
  Use this skill whenever the user asks to write, generate, or create a
  podcast script or podcast episode, from a topic, or from source material
  such as a news digest, newsletter, email review, or set of articles, and
  optionally convert it to audio with Azure Text-to-Speech. Handles the
  initial request and every follow-up refinement (source, topic, length,
  cast, narration) in the same task.
That last sentence exists because of a bug I spent too much time on. Without it, the Skill worked cleanly for “make this a podcast,” then quietly fell out of context when I said “actually, make it shorter,” and the agent improvised a script with none of the rules applied. Explicitly saying that the Skill owns follow-ups fixed it.
What the Skill actually does
The interesting part is not “generate a podcast,” but the sequence. The Skill guides the agent through 11 steps, and that order keeps the output from turning into mush.
It parses before it writes. Given source material, the first pass extracts every distinct item: headline, publication, date, core factual claim, figures or quotes, and the “so what.” Duplicates covering the same event are merged. Footers, disclaimers, unsubscribe text, and image captions are discarded. This step alone is why output from a real newsletter is usable, because real newsletters are about 30 percent boilerplate.
It makes an editorial decision. The remaining items are ranked by newsworthiness and impact. The top four to six get full segments, and everything else is swept into one rapid-fire round. That is the difference between an episode and a list, and it is the step most people skip when they try this with a one-shot prompt.
It writes for a mouth, not an eye. Contractions everywhere. Most lines are under 30 words. Long explanations are split across two or three exchanges so the other host can interject. One concrete analogy per complex idea. One host regularly asks the question the listener is thinking, and the other unpacks it.
There are guardrails, and they matter. Reactions to facts are fine. “That number is wild” is fine. Invented opinions about people, companies, or politics are not. Unconfirmed claims are flagged out loud: “the report explicitly calls this unconfirmed.” Headlines are never read verbatim; they are paraphrased into speech. Sources are attributed by name.
It budgets length as a real target. Everything is costed at roughly 150 spoken words per minute. Short is about 450 words, medium about 900, and long about 1,800, and the agent tries to land within 10 percent. Six minutes means six minutes. That matters a lot when you are building a habit around a fixed commute.
The cast
Two recurring hosts, always with the same personalities:
- Nova is the lead. Warm, curious, quick. She drives the agenda, asks the question the listener is thinking, and reframes jargon into everyday language.
- Miles is the analyst. Calm, dry, precise. He supplies context, numbers, caveats, and second-order implications. He occasionally pushes back on Nova.
Neither is a narrator. They talk to each other, not to the microphone. There is no “welcome to the podcast,” no channel branding, no music cue. The episode opens cold on the single most surprising fact in the material. That is the right way to open anything.
You can override all of it: different names, different voices, a single host, a different language. Nova and Miles are just defaults so you do not have to decide.
Running it
Paste the digest into the agent and ask:
Here's this morning's press review. Make it a six-minute episode
and give me the audio.
The agent parses, ranks, and writes both files, then shows a table with segments and rough running time before asking whether to generate audio. Keep that review step. It is much cheaper to fix the running order in text than after synthesis.
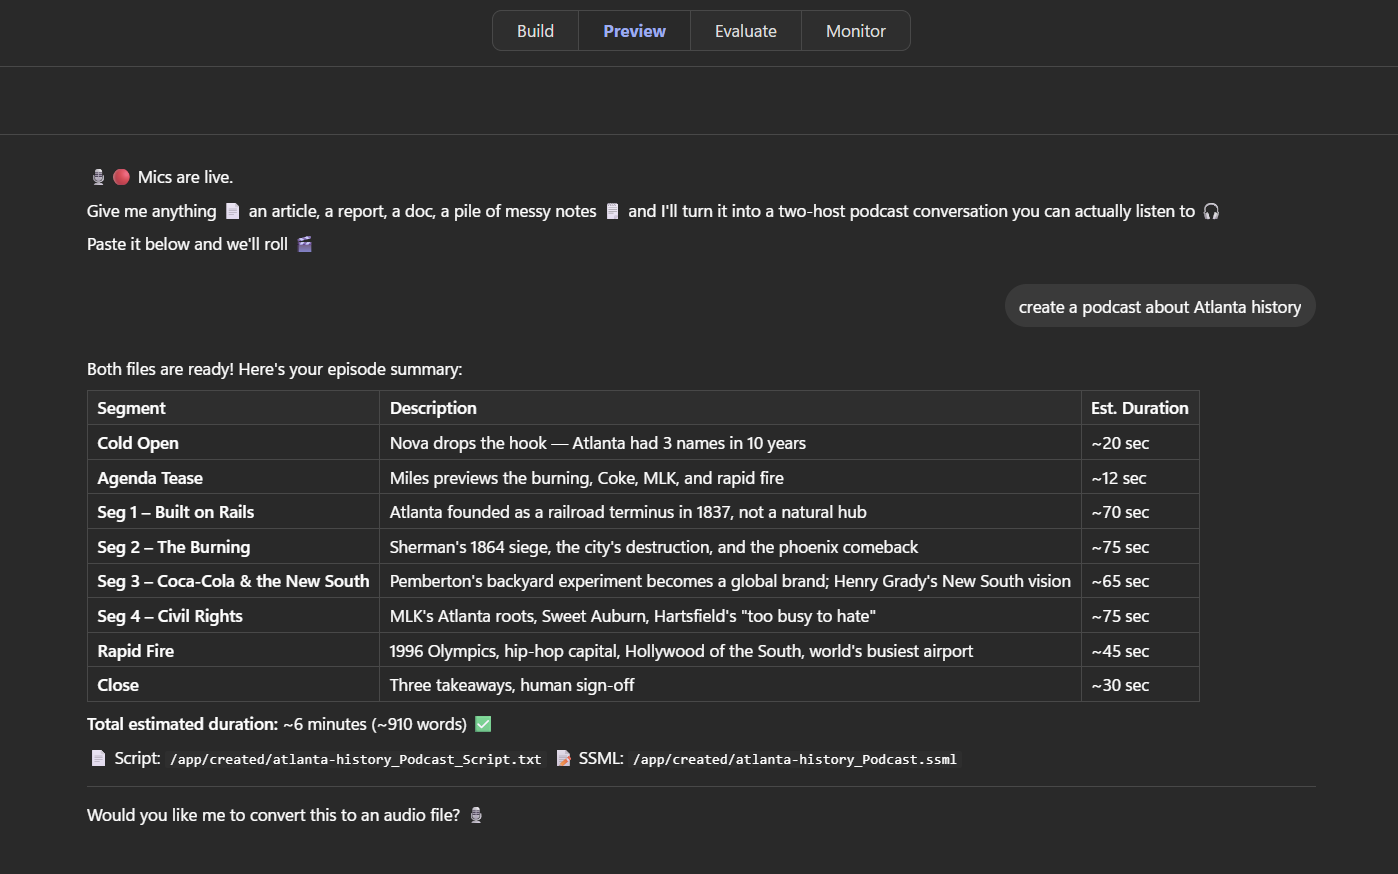
When you approve, the agent sends the SSML to ConvertTextToSpeechWithSSML with outputFormat: riff-24khz-16bit-mono-pcm, decodes the base64 response, and saves it as a downloadable .wav file.
Part 4: Getting it onto your phone
This is the part that turns a demo into a habit, and why it is worth building instead of running a simple prompt.
Publish the agent, then enable the Microsoft 365 Copilot and Microsoft Teams channels under Channels. Henry’s post on Teams and M365 Copilot deployment covers both channels in detail, so I will not rehash the admin approval flow here.
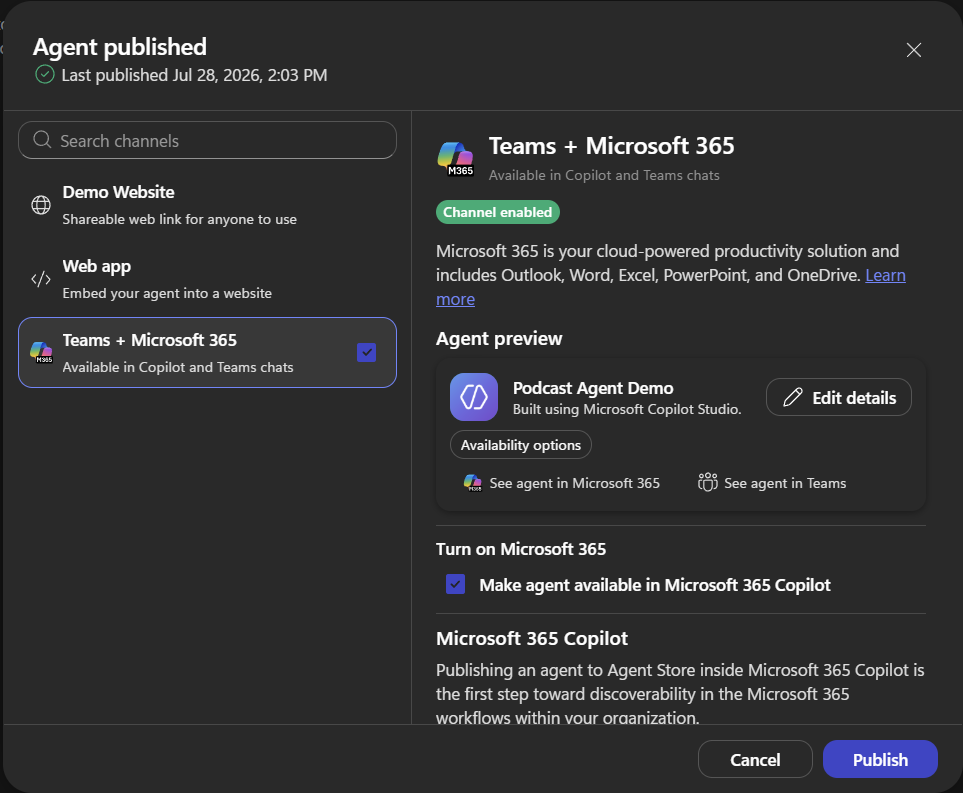
This gives you the part that actually matters. Teams mobile renders the returned .wav file as a playable attachment, so a weekday morning looks like this:
- Forward or paste the press review to the agent in Teams on your phone
- Put the phone in your pocket and put on your coat
- By the time you are at the door, the audio is waiting in the chat
- Tap play, put on headphones, and walk
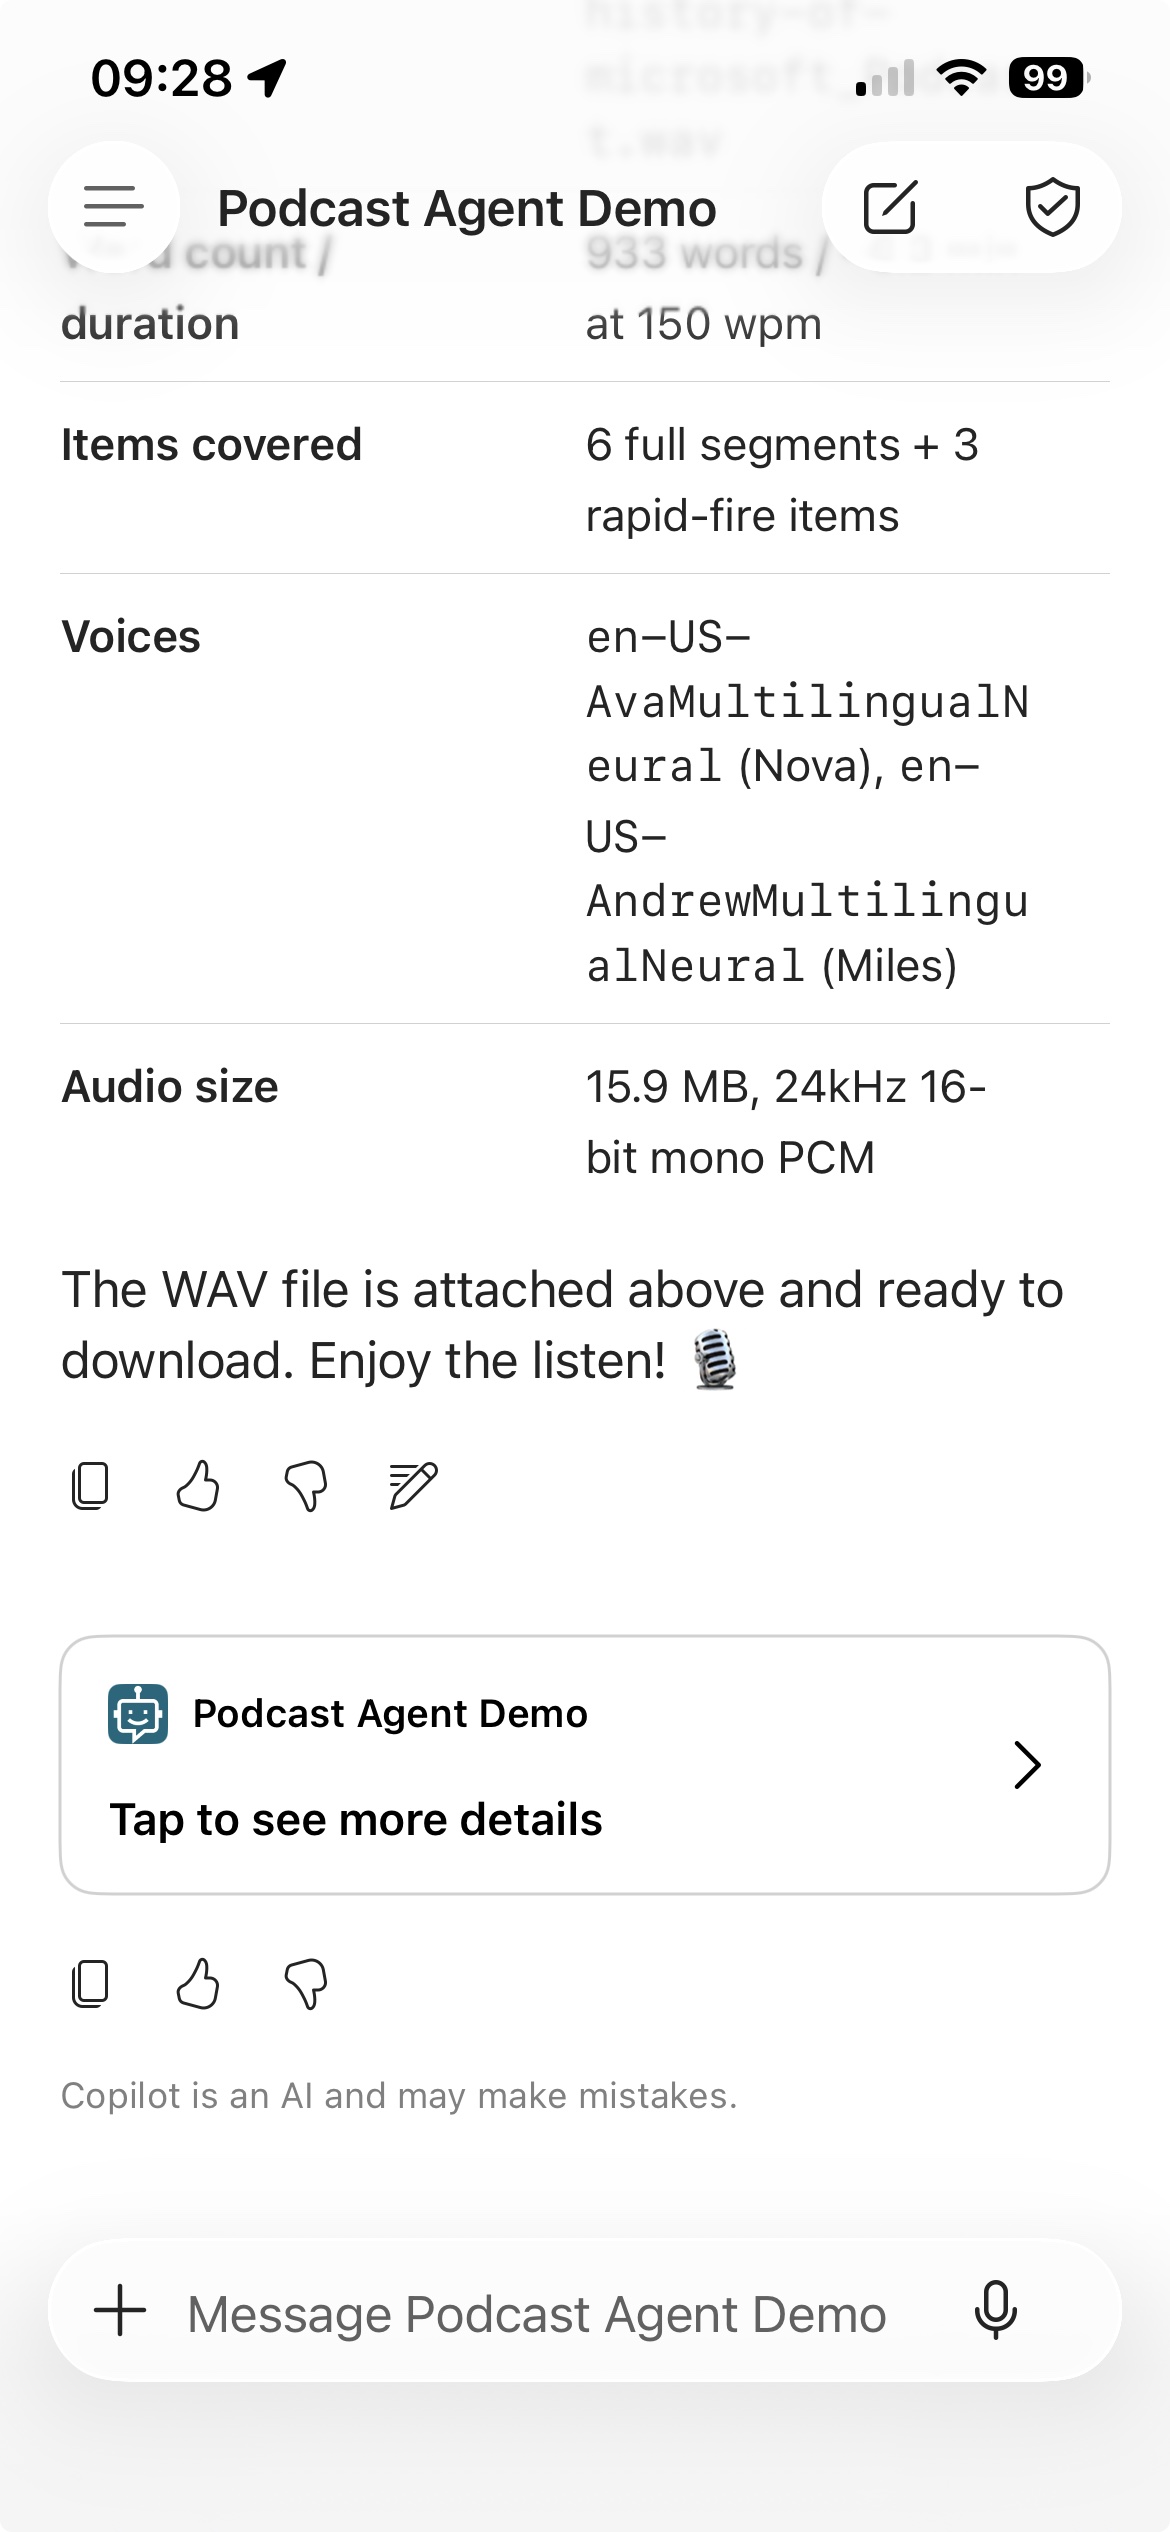
Audio playback behavior differs across channels. Teams mobile handles attachments well, but other channels may provide a download instead of a player. Test on the channel you will actually use before building a morning routine around it.
The part that decides whether it sounds good
Everything above is plumbing and editorial. This part is mechanical, and it is where the first attempts failed.
Spell out anything the synthesizer will mangle
TTS engines are confidently wrong about symbols. So numbers and abbreviations do not survive unchanged in the spoken text:
- “twenty twenty-six” instead of
2026 - “three point two billion dollars” instead of
$3.2B - “about fifteen percent” instead of
~15% - Acronyms are expanded on first mention, then abbreviated afterward
- Letter-by-letter acronyms use
<say-as interpret-as="characters">API</say-as> - Odd proper nouns use
<sub alias="phonetic spelling">Name</sub> - French phrases inside English lines are wrapped in
<lang xml:lang="fr-FR">
No smart quotes, em dashes, asterisks, underscores, or URLs. All of them either get read aloud in unexpected ways or quietly break the XML.
One voice element per turn
This is the rule that cost the most time, so I will be direct.
In a multi-voice SSML document, a <break> element placed directly between two <voice> elements is invalid and synthesis fails. Not “sounds odd” — fails. The pause you want between turns must live at the end of the previous turn’s text, inside that turn’s <prosody>. Two <voice> elements should sit directly next to each other.
<speak version="1.0"
       xmlns="http://www.w3.org/2001/10/synthesis"
       xmlns:mstts="http://www.w3.org/2001/mstts"
       xml:lang="en-US">
  <voice name="en-US-AvaMultilingualNeural">
    <mstts:express-as style="excited">
      <prosody rate="+8%" pitch="+3%">Okay, so the number that stopped me cold
      this morning was forty percent. <break time="300ms"/> Forty percent, in one
      quarter. <break time="250ms"/></prosody>
    </mstts:express-as>
  </voice>
  <voice name="en-US-AndrewMultilingualNeural">
    <mstts:express-as style="chat">
      <prosody rate="-2%" pitch="-4%">Right, and the part everyone's skipping is
      that it's off a very small base. <break time="250ms"/> Context matters
      here. <break time="700ms"/></prosody>
    </mstts:express-as>
  </voice>
</speak>
Notice the trailing breaks. 250ms is the gap before the next turn. 700ms is the longer gap before the next segment. Nothing sits between the two <voice> elements.
Vary the delivery or it goes flat
Applying a single rate and pitch to the whole document sounds like an airport announcement. The Skill sets a baseline per host: Nova at rate="+6%" pitch="+2%", Miles at rate="-2%" pitch="-4%". Then it nudges them line by line to match the emotion of the sentence.
<mstts:express-as> does the rest: chat for banter, friendly for explanation, narration-professional for the factual core of a story, and excited used sparingly for the cold open. Styles are optional rather than structural because unsupported styles are silently ignored by the service. If you swap in a voice that does not support excited, you lose a little color, not the whole episode.
<emphasis level="moderate"> is used for only one or two key terms per segment. More than that, and emphasis stops meaning anything.
Before debugging anything in Copilot Studio, paste the generated SSML into Audio Content Creation in Speech Studio. It tells you exactly which line is malformed, which the connector does not.
Trade-offs, honestly
It is not instant. Parsing, ranking, writing, and synthesizing a six-minute episode is real work. This is a “kick it off and go put your shoes on” operation, not a chat response.
Long episodes need splitting. SSML is kept under 40,000 characters. If an episode exceeds the limit for a single synthesis call, the agent splits it at segment boundaries, synthesizes each part, and stitches the decoded audio together in order. It works, but it has more moving parts.
Editorial judgment is still judgment. Ranking is the agent’s opinion about what matters in the source material. It is usually reasonable and occasionally wrong. That is why the Skill shows the segment table before narrating anything. Reorder it if you disagree.
Garbage in, confident garbage out. If the source material is thin, you get six minutes of two people being enthusiastic about very little. The Skill will not invent facts to fill time, but it also will not tell you that your newsletter was boring.
Where this goes next
The obvious extension is removing me from the loop completely. Add an autonomous trigger to the inbox, run the Skill when the press review arrives, and save the .wav file to a OneDrive folder that is already synced. Giorgio’s meeting transcript analyzer is basically that structure already, just aimed at a different problem. I have not wired it up yet. I wanted to be sure the output was good enough before automating it, and now it is. That is next weekend’s project.
Another direction is source material that is not news. Release notes for a product you do not follow closely. Changelogs for a repository you occasionally contribute to. That architecture document nobody read. Things where the information is genuinely useful but the format is genuinely hostile, which accounts for a depressing amount of what lands in a work inbox.
If you want to see how far Skill instructions can be pushed, this Skill is a good stress test. It asks the agent to do editorial work, creative writing, and strict XML generation in a single pass, and the constraints slightly conflict with each other. Watching where it creaks taught me more about writing Skill instructions than a polite Skill would have. Incidentally, the way I first found the SSML failure was by making the agent narrate its own steps, which is the first trick covered in the post about topics.
So: what are you still failing to read in your inbox? Point the agent at that first.