Review Before Release: Using Agent Review Tool for Copilot Studio Agents
How to use Agent Review Tool before releasing Copilot Studio agents to investigate review findings, understand Skill quality, and inspect relationships between components.
Translated article — This article is based on Review Before Release: Using Agent Review Tool for Copilot Studio Agents by ramakrishnan24689 (@ramakrishnan24689) on The Custom Engine (2026-08-18). The original wording takes precedence.
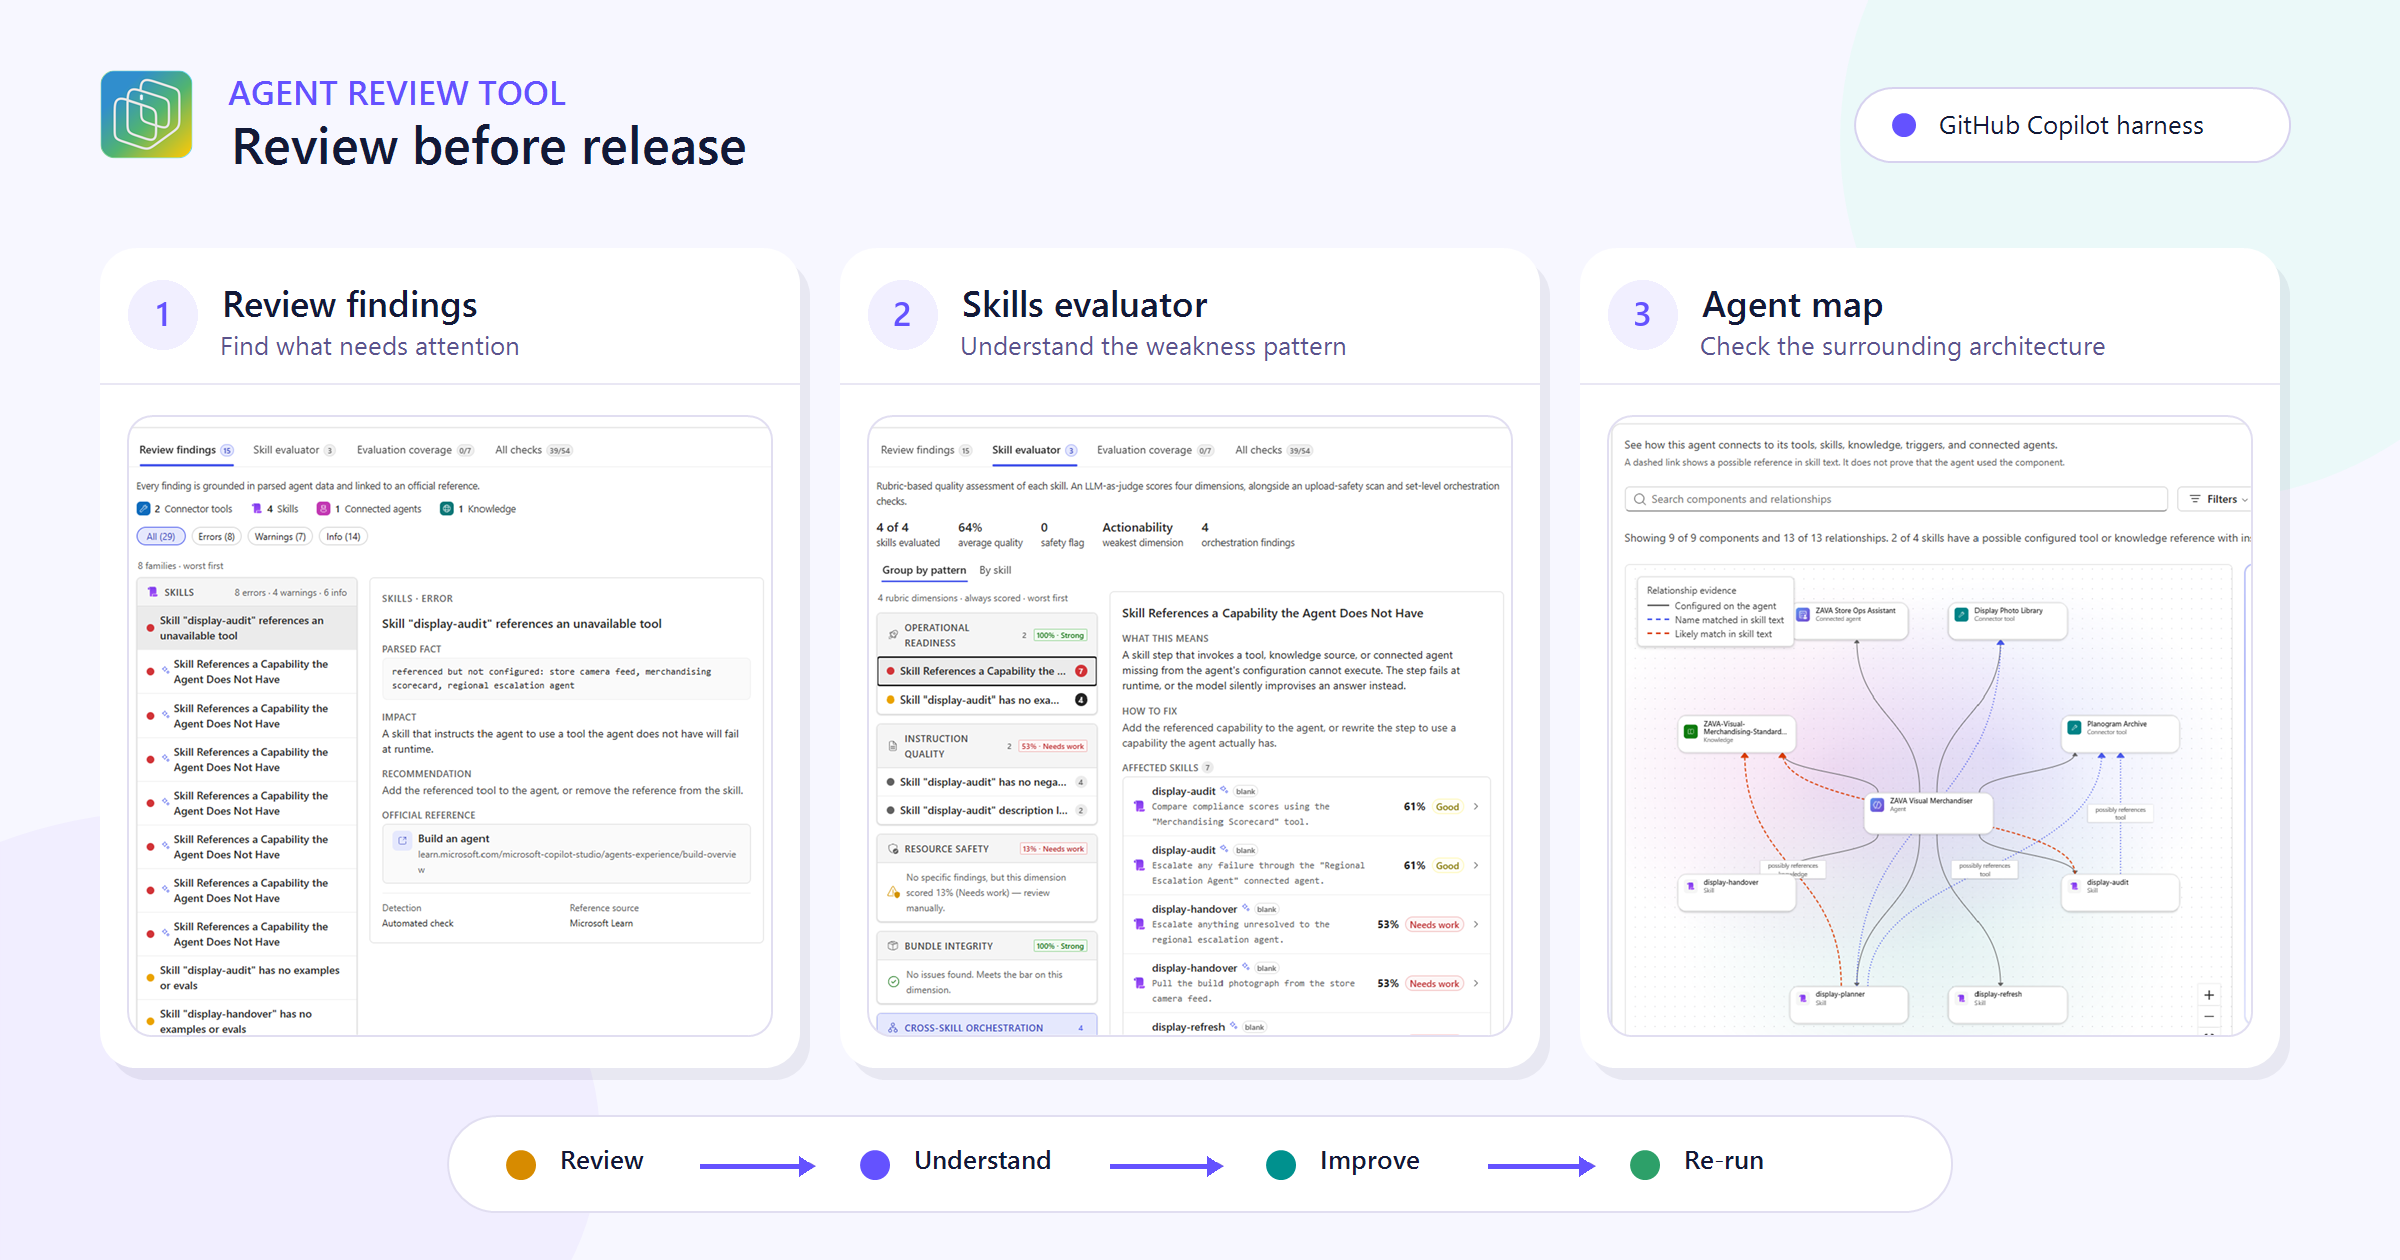
Your agent behaves as expected in the Preview tab. It answers the questions you expected, calls the right tools, and appears ready to move to the next environment.
But before release, how do you systematically review its instructions, Skills, tools, knowledge sources, evaluation coverage, and connected-agent architecture?
Everything is easy to inspect when an agent has one instruction and one Skill. Agents rarely have the courtesy to stay that small.
As an agent grows, its configuration spreads across several surfaces. A Skill can be perfectly reasonable on its own but overlap with another Skill. A tool can be configured correctly but referenced ambiguously. A knowledge source can exist without the Skill giving the agent enough direction to use it. Preview may not expose these issues until the right combination of inputs appears.
Agent Review Tool, part of Copilot Agent Kit, provides a repeatable way to inspect those risks. This article uses ZAVA Visual Merchandiser, a fictional retail visual-merchandising agent powered by the GitHub Copilot harness in Copilot Studio. We will walk through a practical pre-release workflow focused on three capabilities:
- Review findings, which organize grounded checks by severity and rule family
- Skill evaluator, which assesses individual Skill quality and cross-Skill orchestration
- Agent map, which helps inspect how reviewed Skills relate to tools, knowledge sources, and other components
This is not a tour of every button in Agent Review Tool. It focuses on one question: what should a maker inspect and improve after an agent works, but before it is released?
As of August 18, 2026, Agent Review Tool is available as a preview experience. Its evaluators and presentation may evolve.
Why the Preview tab is not enough for review
Testing conversations is essential, but a conversation exercises only the path selected for that input. It does not automatically tell you whether:
- two Skills have overlapping responsibilities
- a Skill description helps the agent decide when to use it
- instructions define boundaries and escalation behavior
- configured capabilities have representative evaluation coverage
- a Skill references a tool or knowledge source clearly enough to be maintainable
- an architectural relationship is configured, inferred from authored text, or actually observed at runtime
Agent Review Tool complements runtime testing by inspecting the saved configuration and producing findings a maker can investigate.
| Review method | Question it helps answer |
|---|---|
| Preview and evaluations | Did the agent behave as expected for this conversation? |
| Agent Review | Does the saved configuration contain quality, clarity, coverage, or maintainability risks? |
Neither method certifies that an agent is production-ready. Used together, they provide a more useful picture than either one alone.
If you are new to the broader toolkit, the overview linked above explains how the maker and administrator experiences fit together.
Establish a baseline review
ZAVA Visual Merchandiser is a fictional agent created for this walkthrough, not a downloadable sample. The screenshots use fictional names and omit tenant-specific details. The August 18, 2026 review was chosen because its findings were specific enough to understand, change, and review again.
In Agent Review Tool, find the agent and start a review. The review combines deterministic checks and AI-supported analysis against the available configuration. Findings are grounded in the evidence collected for that review.
The completed review opens a workspace with three main sections.
- Review, containing findings, Skill evaluator, evaluation coverage, and the complete check inventory
- Agent map, showing the reviewed architecture as a graph and a list
- Cost & efficiency, providing bounded observed-activity signals, improvement and validation guidance, and planning ranges
This article covers only the first two sections. Cost and efficiency deserves its own discussion because planning ranges and observed activity have different evidence boundaries from configuration review.
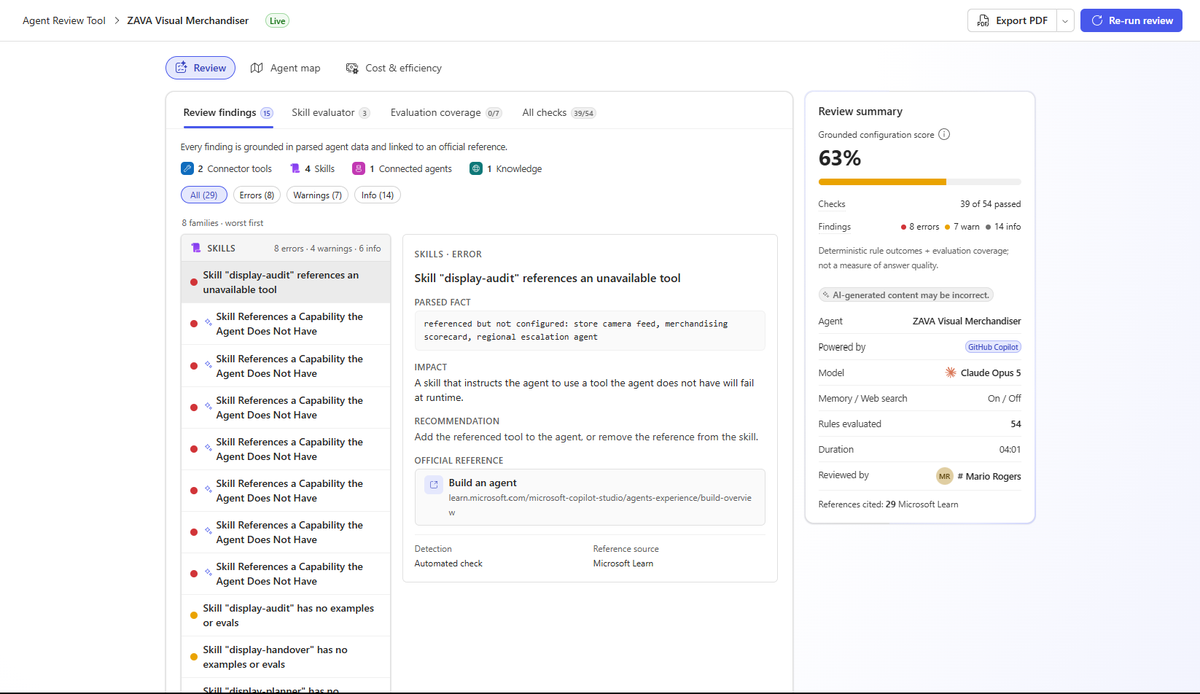
Start with findings, but do not stop at the score
The review summary shows a score and a breakdown of errors, warnings, and informational findings. The score is a useful summary, but the individual findings and evidence tell you what to investigate and improve.
For agents powered by the GitHub Copilot harness, the grounded score uses deterministic, rule-based pillars for evaluation readiness and instructions, with additional pillars when the agent includes Skills, tools, knowledge sources, or connected agents. AI-supported findings appear as supporting review evidence, but they do not replace the deterministic pillar scores.
A high score does not prove runtime quality, and a low score does not prove that the agent will fail. Use findings to decide what to investigate and which evaluations to run next.
Before changing anything, record the baseline.
- Overall score
- Errors and warnings
- Number of Skills evaluated
- Weakest Skill dimension
- Cross-Skill orchestration findings
- Evaluation coverage for configured capabilities
This gives you a more useful comparison point than “it looks better” when you run the review again.
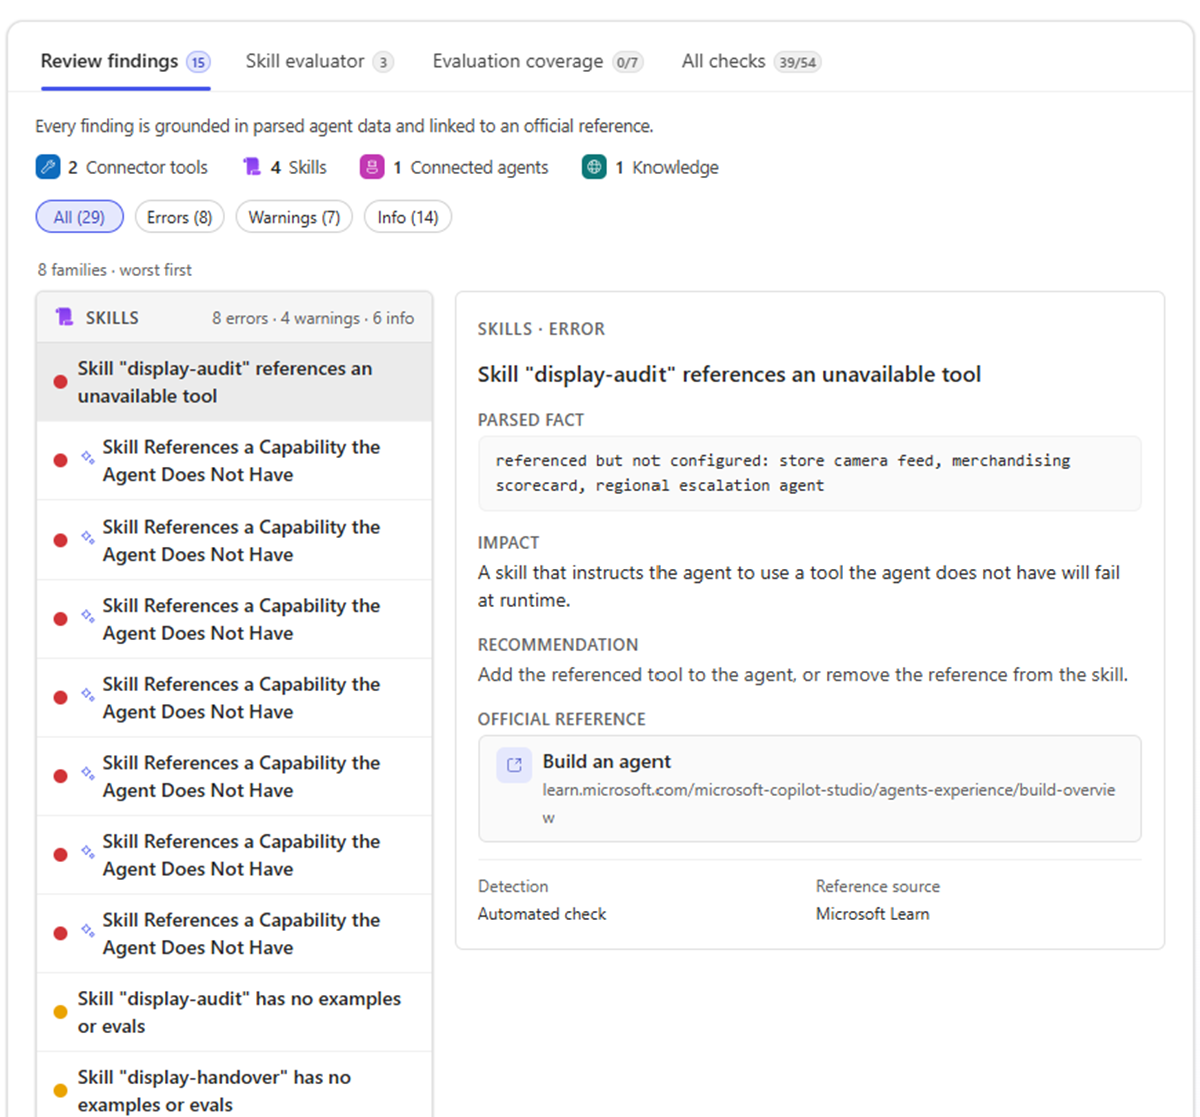
Use the Review findings view for triage
Open Review findings first. The capability inventory summarizes what was captured, and severity filters narrow the results. Findings are grouped by rule family. Selecting one opens its evidence, rationale, recommendation, possible fix steps, and supporting references.
This is the fastest place to answer three initial questions.
- Which findings need attention before this release?
- Which capability or configuration area produced them?
- Is the evidence specific enough to verify in the agent?
Review findings tell you what deserves investigation. Skill evaluator helps determine whether the issue is isolated or repeated across the Skill set, and Agent map provides the surrounding configuration context.
Inspect Skill quality by pattern
Open Skill evaluator. The default Group by pattern view organizes results across all evaluated Skills and summarizes average quality, safety flags, the weakest rubric dimension, and cross-Skill orchestration findings.
Instruction quality is assessed across four rubric dimensions.
| Dimension | What to look for |
|---|---|
| Clarity | Does the description say when the Skill should be selected, using concrete and unambiguous language? |
| Actionability | Are the steps executable, ordered, and clear about required inputs, outputs, edge cases, and validation? |
| Scope discipline | Does the Skill perform one coherent job with clear boundaries and no unrelated responsibilities? |
| Composability | Can it work with parent instructions and sibling Skills without overlap, contradiction, or hidden dependencies? |
The same view also reports Bundle integrity, Resource safety, and Operational readiness. These results are separate from the four instruction-quality dimensions.
For agents powered by the GitHub Copilot harness, Skill quality is especially important because it is not just about what is inside one SKILL.md. The agent also has to distinguish that Skill from every other available option.
For a deeper introduction to Skills for agents powered by the GitHub Copilot harness, see Agents Have Skills Now.
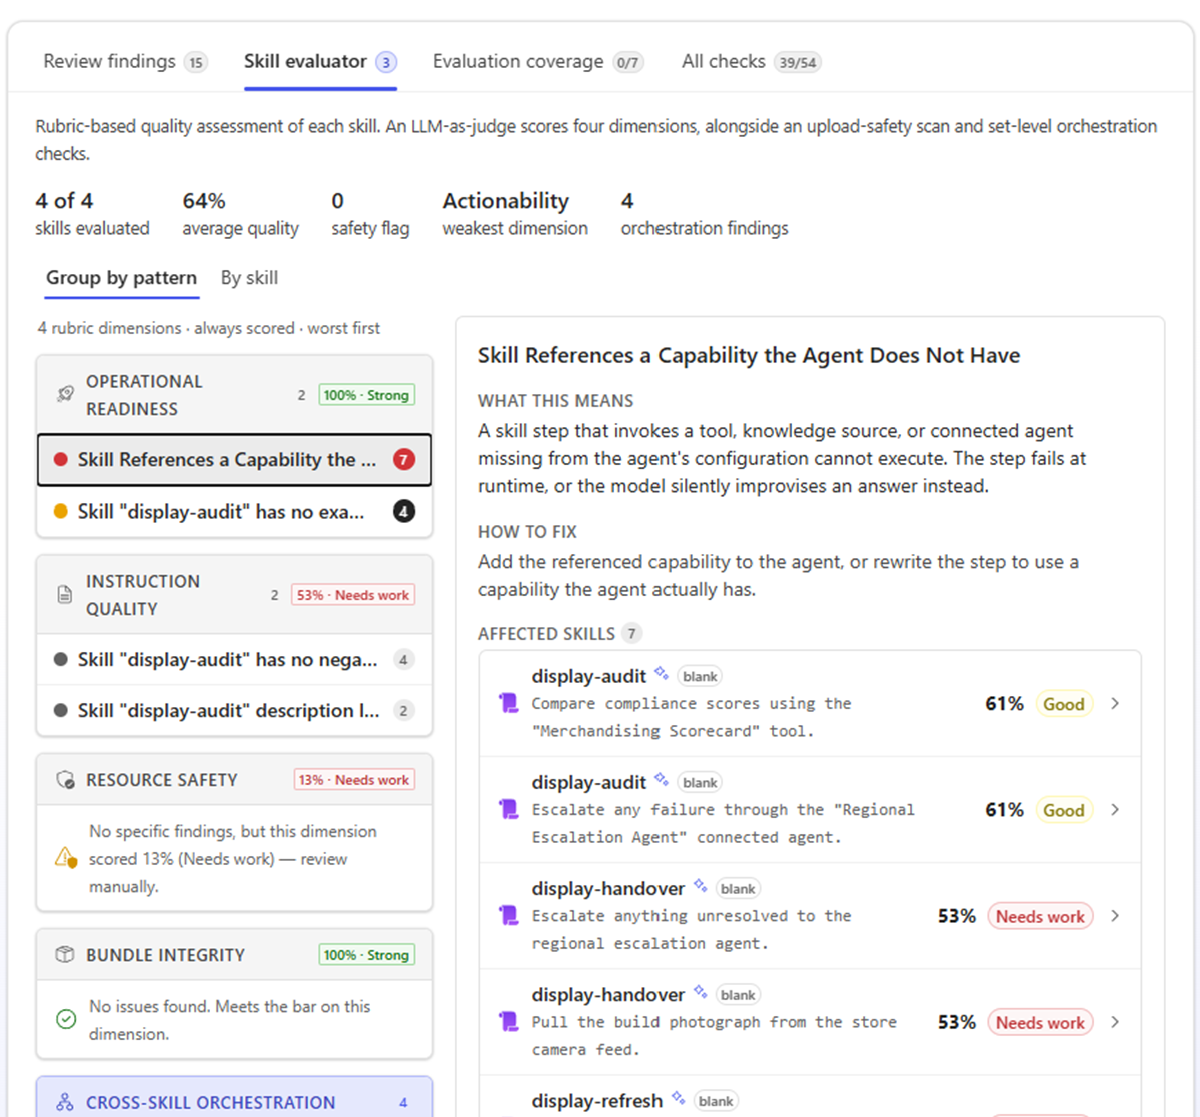
Use “By skill” to find the actual change
The grouped view tells you whether a weakness is repeated. By skill tells you where to make the change.
For ZAVA, display-audit was the problem. Two of its five steps mentioned Merchandising Scorecard and Regional Escalation Agent, but neither capability was configured on the agent. Agent Review marked this as Skill References a Capability the Agent Does Not Have. The Skill scored 4/10 for Actionability and 61% for instruction quality.
That gave us a concrete problem to solve: as written, the agent could not complete the compliance scoring or escalation steps.
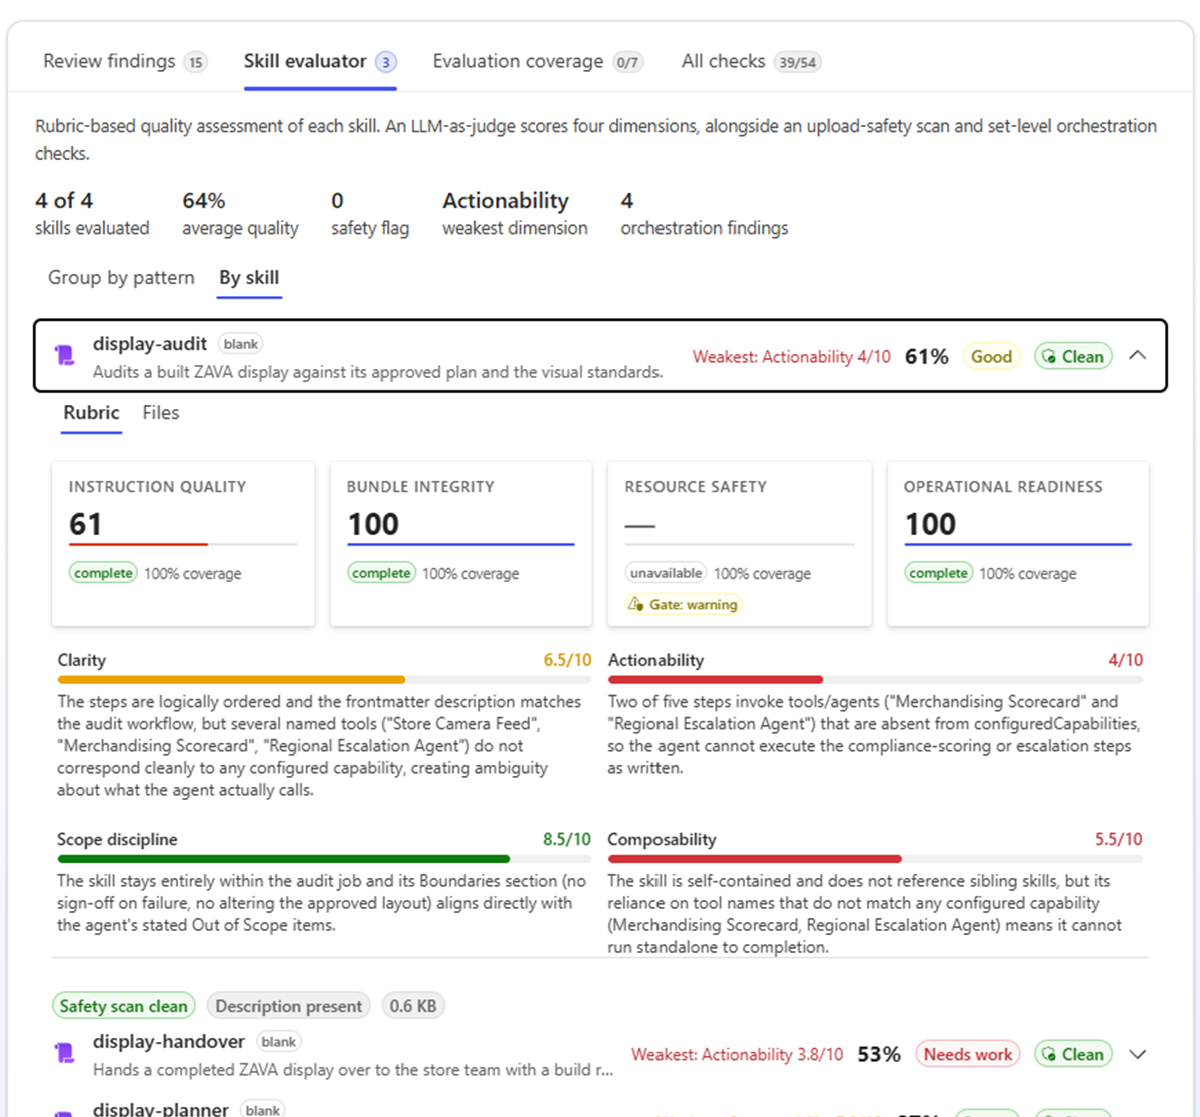
A useful finding points to the instruction or Skill text that caused the concern, making it easier for a maker to verify and fix. If an AI-supported evaluation is unavailable, Agent Review shows that status instead of treating the check as passed.
Use Agent map to inspect the surrounding architecture
Skill findings are easier to understand in architectural context. Open Agent map to inspect the components captured in the saved review.
The map includes supported components captured during the review. Search and filters narrow the graph, while Map and List provide visual and semantic views of the same filtered information.
For the ZAVA finding, filter the map to the affected Skill and related tools or knowledge sources, then ask:
- Is the referenced capability actually configured on the agent?
- Does the Skill use the configured capability name clearly and consistently?
- Would another maker understand when and why the Skill uses that capability?
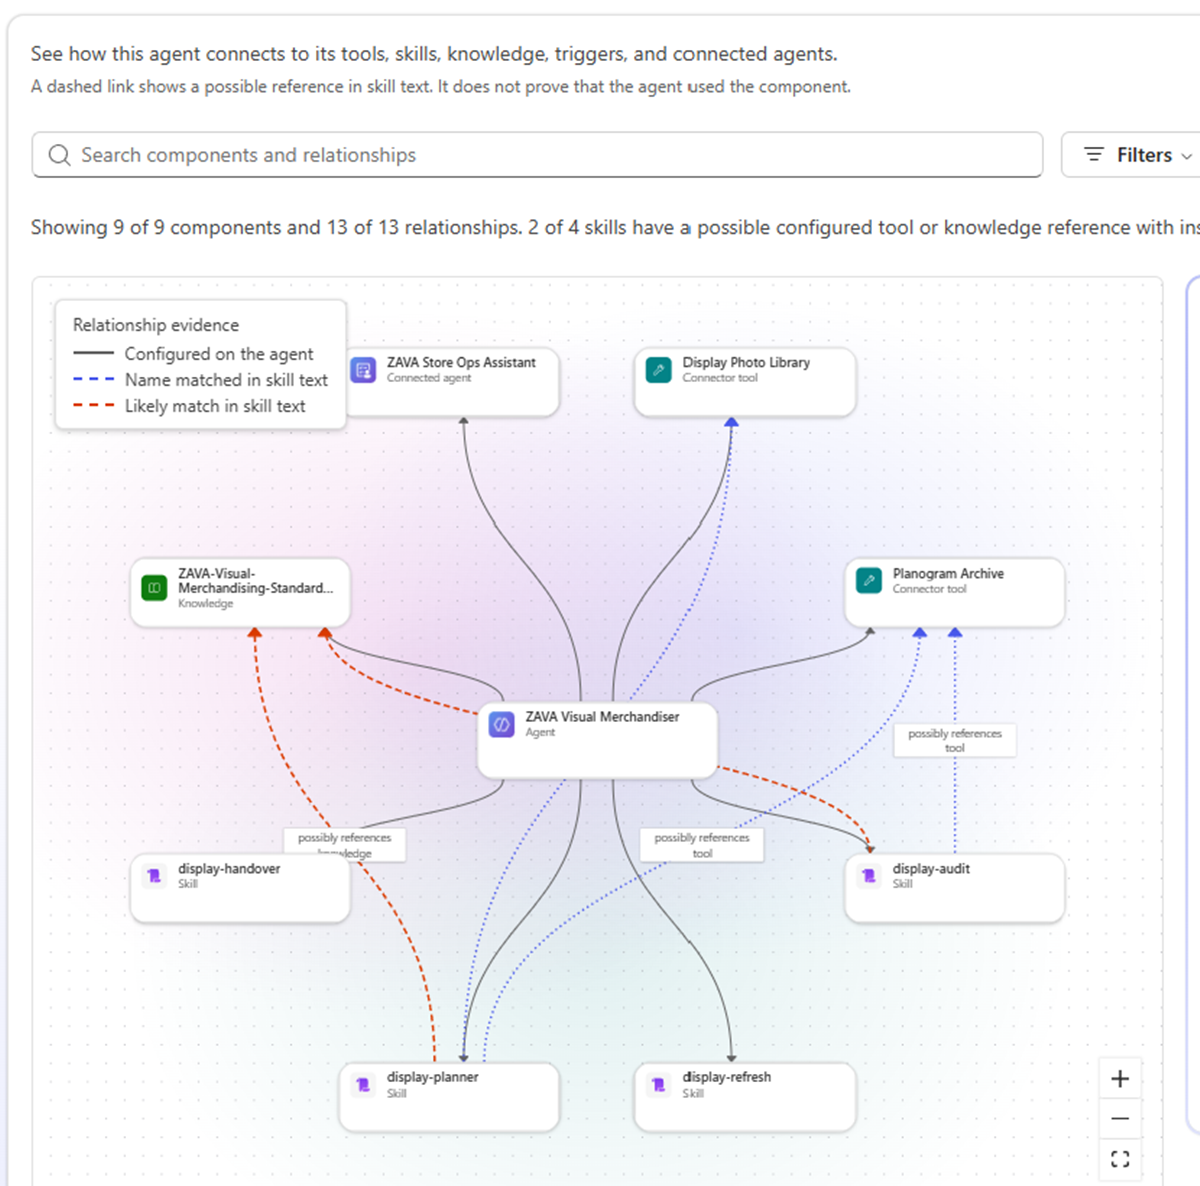
Agent map describes reviewed configuration and bounded authored references. It does not prove that a tool, knowledge source, Skill, or connected agent was invoked, and it does not reconstruct the agent’s runtime plan.
Make one focused improvement
Change only the instructions or configuration implicated by the evidence. Before changing ZAVA, we documented the intended correction and confirmed that it would not alter unrelated behavior.
For display-audit, we chose to rewrite the Skill instead of adding new capabilities.
The exact step text was not retained, so the table below is a conceptual summary of the verified change rather than a verbatim before-and-after transcription. It illustrates the remediation pattern, but it is not copy-ready Skill guidance.
| Baseline issue | Implemented correction |
|---|---|
| The Skill referenced Merchandising Scorecard and Regional Escalation Agent, neither of which was configured on the agent. | The affected steps use configured capabilities: Planogram Archive, Display Photo Library, the ZAVA visual-merchandising standards knowledge source, and ZAVA Store Ops Assistant. |
This change directly resolves the evidence because every referenced capability now exists on the agent. It also preserves the original purpose: inspect a display, evaluate it against available merchandising standards, and route follow-up through a configured assistant.
After the update:
- Run the conversations and evaluations most likely to exercise the changed Skill.
- Confirm that routing and outputs still behave as intended, then run Agent Review again.
- Compare Skill dimensions, orchestration findings, and supporting evidence against the baseline.
- Reopen Agent map to confirm that the configuration view still reflects the intended architecture.
| Metric | Baseline review | Second review |
|---|---|---|
| Grounded configuration score | 63% | 67% |
| Checks passed | 39 of 54 | 51 of 54 |
| Errors | 8 | 0 |
| Warnings | 7 | 2 |
| Average Skill quality | 64% | 90% |
| Evaluation coverage | 0 of 7 | 0 of 7 |
The targeted unavailable-capability finding no longer appeared. However, evaluation retained a fixed 30% weight in the pillar-weighted grounded score, so the missing test coverage continued to limit the result even with 51 of 54 checks passing.
The final display-audit instruction-quality result was not included in the retained evidence, so this comparison does not claim a precise Skill-specific change. This walkthrough also did not retain runtime evaluation results. The evidence shows that the configuration finding was resolved; it does not prove runtime behavior improved.
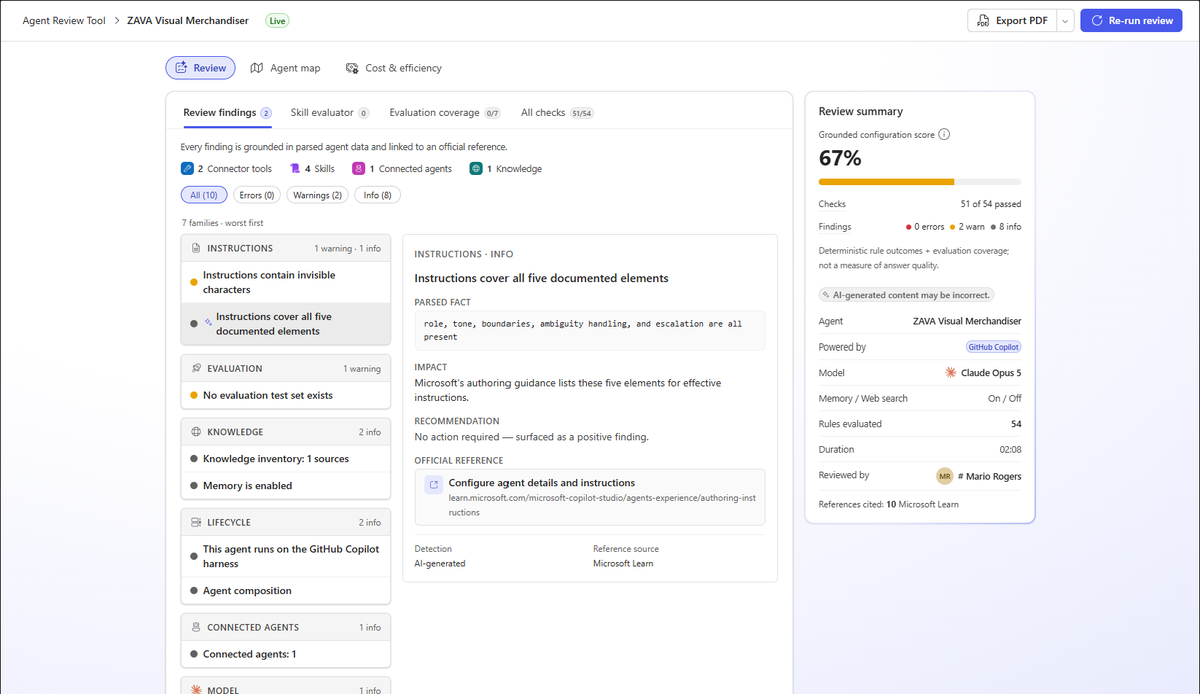
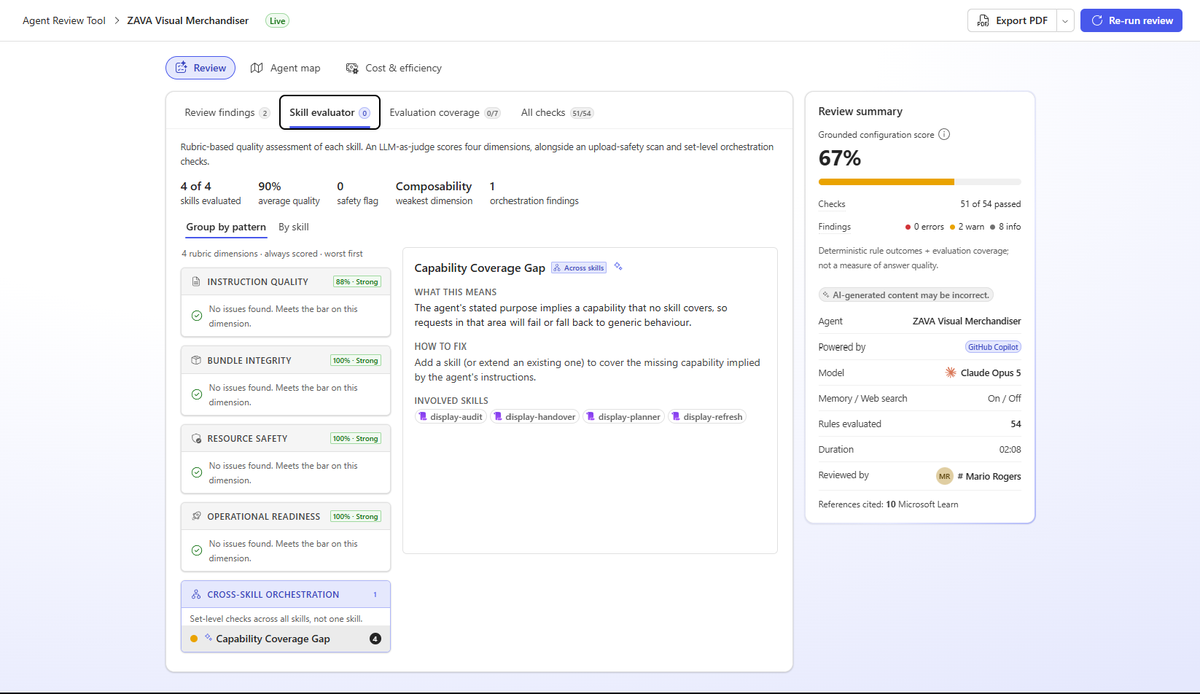
Resolving the unavailable-capability error exposed the next review priorities; it did not empty the findings list. The two remaining warnings concerned the missing evaluation test set and instruction character hygiene. Skill evaluator also surfaced one Capability Coverage Gap across the four Skills. These items were outside the focused change in this walkthrough.
If a finding disappears but runtime evaluations regress, you improved the review result, not the agent. The goal is not to win points; it is to leave the agent clearer, more reliable, and easier for the next maker to understand.
This is also why a single model-generated rating is not enough. The better LLM scoring pattern explains why smaller evidence-backed checks and deterministic combination rules are more defensible than asking a model for one opaque score.
What Agent Review Tool does not claim
Agent Review Tool guides investigation. It does not certify an agent as production-ready, modify the source agent, replace representative test cases or human review, or prove that a configured capability was invoked. The cost-planning and observed-activity views also do not report actual billed spend or guarantee savings.
Conclusion
An agent that behaves as expected in the Preview tab is ready for deeper review, not necessarily ready for release. Agent Review Tool brings findings, supporting evidence, Skill quality, evaluation gaps, and configuration relationships into one workflow so makers can move from “it seems fine” to focused, traceable improvement.
Agent Review Tool is available through Copilot Agent Kit on Microsoft Marketplace. Installation and access requirements are covered in the Agent Review Tool reference guide, so this workflow can focus on reviewing the agent rather than setting up the toolkit.
Use it alongside representative evaluations. Establish a baseline, inspect the evidence, make one focused change, and review again. The outcome matters more than the score. The configuration should become clearer, and runtime behavior must be validated separately.
What is the hardest part of pre-release review for your agents: Skill boundaries, evaluation coverage, or understanding the configured architecture?